Forgot your password?
typodupeerror

Comment Re: Not terrible, which is too bad (Score 2) 44

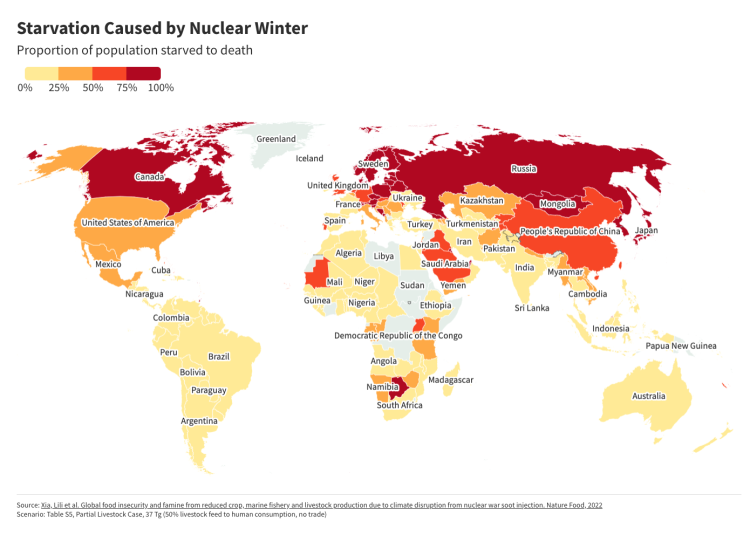
Map of agricultural production changes in the nuclear winter following a minor nuclear exchange, posted for no particular reason.

(For a full-scale exchange...)

Also, for no particular reason, a map of Russia's population distribution, alongside a reminder of Russia's nuclear missile failure rate, particularly booster failures. And that nuclear warheads have been commonly lost disturbingly often even during peacetime, with at least seven weapons from four incidents lost in flight landing in a way that left them fully intact and easily reparable, just from the US alone. And that Ukraine is rich in nuclear engineers, including still some retirees who worked in the Soviet nuclear weapons programme.

There's also this myth that "if you just use a nuclear weapon, you automatically win the war". Nuclear weapons are immensely effective terror weapons, but their effectiveness on the front is a lot weaker than most people think. People on frontlines tend to be in trenches, bunkers, basements, armoured vehicles, etc, and can be surprisingly close to a tactical nuclear blast while still surviving. They're effective against hard points but struggle against a broad, diffuse front (aka, today's front, which is a sparsely populated, deep, amorphous zone, thanks to drones). Amortizing Russia's estimated budget for tactical nuclear weapons comes up with ~$15-25M per weapon (not counting the delivery system), so they're hardly a dime a dozen either.

IF, via terror bombing or threats of terror bombing, you can convince your enemy to surrender, then congratulations, you have won (enjoy your nuclear waste heap and restive population who wants nothing more than to kill you). If they do not, however, their only goal remaining will be to focus 100% on using their extensive nuclear waste supplies rich in plutonium, their extensive long-range strike weapon supplies, and their extensive metallurgical experience, to render your major cities to ash in the same way that you did theirs.

(I also just assume herein that Ukraine doesn't actually have a secret nuclear weapons programme already, which is certainly an assumption).

Comment Useful but a lot of tokens and security issues (Score 2) 27

Taking meeting minutes could seriously be useful. Sure you can tell claude not to take notes until you say okay let's start the meeting, etc. Though, how much sensitive info gets discussed in meetings? Maybe some should not be broadly shared within the org let alone go into the AI cloud. And how many tokens get burned per meeting? Sounds like a lot.

Comment Re:More drinking their own koolaid... (Score 1) 26

To be clear: you can still totally argue about qualia, sentience, things of that nature. What is not up for debate is that they work through unimaginably-complex chains of logical reasoning on superpositions of conceptual states and engage in forward-planning and metacognition. These are just demonstrable facts.

Comment Re:More drinking their own koolaid... (Score 1) 26

Maybe, maybe not. Personally I perceive some element of logic/reasoning at the level of "useful but not reliable for work" though it may be embryonic and clouded by statistics and hallucinations. At the risk of everyone repeating your argument right up to the day Skynet is born, please create a usable benchmark test to score your definition of "thinking". We can put invertebrates, pets and humans of various IQs on the scale. Then we will clearly see which goal posts must be moved so that machines cannot "think".

Comment Re:Exhausting (Score 2) 97

Members of Congress don't get security clearances or undergo formal background checks. If they're on certain committees, they have a need to know, and they're expected to keep secret information secret or lose their committee membership and possibly be expelled from Congress. On rare occasions, the entire Congress gets briefed in closed session on classified topics.

Comment Re:GPL MIT BSD - Each project can pick what they l (Score 1) 190

Oh- absolutely. For people who want a BSD/MIT license on their work- GPLv-anything is very likely antithetical to your goals if you had selected BSD/MIT as your license already. I was commenting/agreeing that even for someone who is ok with the GPLv2 on their commercial hardware (which is many people), v3 presents a particularly extra toxic barrier.

Oh, yeah. GPL V3 is spectacularly unfriendly to commercial development of anything — enough so that Apple created Clang, which has cut GCC's market share almost in half, massively damaging the long-term viability of the FSF's golden goose. And since the release of V3, GPL development has declined massively to maybe a third of what it was before GPL v3.

GPL v3 was widely regarded by almost everyone in the tech industry as a boneheaded move. It still is.

Comment Re: Uhh... Cool? (Score 1) 190

No, it's called "Evidencing The Fact That It's A Widespread Shorthand" (in specific, among Wikipedians, where it's in official terminology as well), a widespread usage that was falsely claimed to not exist.

(I'll also take this opportunity to note: rage about the use of shorthand on "copyvio", but not a word about "algos")

Comment Re: Uhh... Cool? (Score 3) 190

Shorthand should be something that other people actually use

Okay Felicia.

TL/DR: "copyvio" is the Wikipedia-standard shorthand for copyright violation, used both in direct speech and in official templates. If a person says "copyvio", they've probably spent a lot of time hanging out at Wikipedia, where copyright violation is a frequent topic of discussion.

Comment Re:Uhh... Cool? (Score 2) 190

Oh, also, as pointed out further downthread, any LLM with a training cutoff before the license change date is pretty much assured to be okay for use in a cleanroom implementation. Copyright holders cannot make retroactive copyright changes, and open source licenses generally explicitly grant rights in perpetuity anyway. The threat would be new code. But since the cleanroom side has never seen that new code (it was released after the training date), it remains untainted. And training cutoffs generally lag model releases by many months, so not only should all current models be in the clear, but most next-gen models as well (subject to cutoff date verification, and various kinds of nuance such as avoiding RAG, potential post-training contamination, etc - but there's easy ways to guarantee these aren't problems that are present)

Comment Re:Uhh... Cool? (Score 3) 190

First off, you can always just use a LLM with an open training dataset (OLMo, Pythia, etc) to prove that the data isn't in it, and have that handle the "clean" side of the equation.

Secondly, you are under the mistaken impression that a LLM that has been exposed (which, BTW, does not mean "memorized", or even any rough understandings of the workings - ask the LLM (ideally an abliterated one to avoid refusals) to reproduce the original code verbatim, it'll almost certainly fail badly) automatically fails in such a suit. It does not. There is no such thing as "homeopathic copyright contamination". Copyvio requires substantial similarity. LLMs will tend to have common algos memorized, but those are the very things that tend to be simultaneously not copyrightable.

The cleanroom is an evidentiary shield, not a pillar of copyright law. If you can prove that the cleanroom team had no access to the original, then you can prove that they didn't copy it, and potentially get summary judgement. If you can't prove that, that doesn't mean that it's not copyvio, it just means that you instead have to focus on substantial-similarity defenses. Access without substantial similiarity is not copyvio. If you read an open-source codebase, close it, and then later write a new program purely on your own that looks nothing like the original, you had "access", but still did not infringe. The same applies to LLMs - but even moreso, because humans are much better at learning from brief, limited exposures to content than LLMs are. A court will usually apply an "Abstraction-Filtration-Comparison" test - they break the code down into layers (source code, parameters, architecture, algos, etc) (abstraction), remove everything that copyright law does not protect (ideas and common algos, things where there's only a limited number of ways to possibly do it, etc) (filtration), and then compare the creative expression that remains to see if there exists sufficient similarity to count as infringement. It is highly unlikely that a LLM-implemented version will fail that.

(That said, you're talking about a long, expensive legal battle if you get to that point, so you obviously prefer to be able to get summary judgement if you can)

Slashdot Top Deals

DISCLAIMER: Use of this advanced computing technology does not imply an endorsement of Western industrial civilization.

Working...