Comment Re:Will any human can understand the proof? (Score 1) 30
I mean, isn't that the history of the four color theorem proof?
I mean, isn't that the history of the four color theorem proof?
RH is massive within mathematics, but calling NS "niche"... sorry, but in the real world, NS matters much more. Pretty much every major engineering firm on Earth has computers running NS simulations. Anything that advances NS brings us closer to (or outright directly achieves) things with direct real-world impacts (in this case, the former - proving blow-up doesn't directly have real-world impacts, but advancing the diversity of mathematical approaches that can be applied to study of NS offers future potential for solving more meaningful NS problems - turbulence closure, the vanishing-viscosity limit and boundary layer separation, mapping the edge states around the laminar/turbulent flow regime, long-duration flow regime predictability, the chaotic-adjoint problem, fluid structure interaction and multiphase flows, rigorous guarantees for hybrid AI / reduced order solvers, etc).
"A brute force Lean search" - automated proof solvers have a pretty poor record. There are some proofs from that, but broadly, it hasn't yielded much fruit; the space of formal mathematical steps is astronomically large. "A brute force lean search" is usually not a very effective means to solve difficult unsolved proofs that have evaded mathematicians for much of a century. To solve these problems, you need a combination of two things: a lot of time (your "brute force" is not irrelevant), but also broad cross-domain knowledge and excellent high-level reasoning. Brute force alone isn't enough.
The proofs that AI has been creating, overwhelmingly, haven't been hideous monstrosities stitched together from preexisting work on given problems by brute-forcing the gaps in Lean; it's generally deeply novel, innovative approaches to the problems.
That "same guy getting scooped by OpenAI on Navier-Stokes" thing was so much nonsense. OpenAI had no real competitors. They had already solved the forced options C & D for Navier-Stokes, and before them, the unforced Euler problem as a simpler problem before trying Navier-Stokes. Buckmaster was still trying to reach unforced Euler after the forced one. He couldn't have provided a solution because he didn't have it. Buckmaster himself claimed that he was "essentially
I find it so funny that every time an AI solves a major math problem that nobody has solved for much of a century, there's always people waiting in the woodwork to go, "Oh, hey, I was JUST about to solve that long-unsolved problem!" As if the entire mathematical community had sat around twiddling its thumbs for much of a century but only a year or so ago decided to get its arse into gear.
The Turing Test has long been considered highly defective. It also doesn't mean "a person thinks the computer is alive". It means "the person thinks what they're talking to isn't a computer".
If you wrote a program to write out random clusters of adjacent letters, and had people try to guess whether they were talking to a computer or a cat walking on a keyboard, a lot of them would guess wrongly that they were seeing a cat walking on a keyboard. That doesn't mean that any of them think computers are cats, that there's some simulated cat brain running in software - every one of them, on being told that it was a program, will assume "the program just writes random adjacent letters".
The Turing Test and the supposed "ELIZA Effect" are not the same thing. The ELIZA effect argues that humans, encountering chatbot, assumes that the bot has intelligence or other human traits when they don't.. The reality is that humans almost always assume that chatbots are elaborate tricks - even if they enjoy playing with them. It's like attending a magic show - people enjoy engaging in the illusion of the magic, but almost nobody thinks that the magician is actually engaging in real sorcery, regardless of how real it looks. It's "Huh, I can't figure out what trick was used to create that effect, that's amazingly well done!", not "There is no logical explanation, so this person is a literal sorcerer."
If you're looking for a real psychological effect related to AI, look to the AI effect.
The hardware (and electricity, and connectivity) to run those models locally
No. Not "locally". They're provided free from the cloud. To anyone.
Also, there's a number of literally free models you can use. They're not as good and generally rate limited, but they're better than nothing.
It doesn't matter how cheap they are when their use is effectively unbounded. Slop purveyors open 1,000 bug reports or PRs?
These models typically cost on the order of 10-20 cents per MILLION tokens in (assuming cache misses!) and ~50 cents per MILLION tokens out. 1/100th the cost of Fable or Astra, for a task that's far less token-hungry than coding. 1000 bug reports or PRs is perfectly handleable. It simply is not an issue.
Secondly, if there's evidence that a bad actor is involved, a model is perfectly capable of asking you if you want to ban them or banning on its own if you give it permission. And if they're behaving in a way that makes them hard to ban (sockpuppeting, etc), likewise asking you / acting on its own to report the attack.
Where do we send our funding requests?
Right here. Note I'm not going to write your harness for you, but if you come back to me with a harness and a serious proposal, I'll totally look at it.
I can only find a single example in all of history of a person who was fooled by ELIZA, and only in a "he thought it was a remote-working employee taking the piss" way, not in a "he thought a computer was alive" way.
This notion that ELIZA mass-fooled people is simply not in line with the actual reality we live in. Weizenbaum pushed it heavily in his later life because he was an anti-AI zealot (driven in part due to anger about the use of computers for targeting during the Vietnam War, but also because some people started seriously considering the use of a tool like ELIZA/DOCTOR for talk therapy), with his main example being claims that because his secretary wanted to continue using it and asked him to leave the room, she had been stupidly duped into thinking it was alive. Of which Weizenbaum's own daughter later commented:
I always heard that just really kind of soaked in arrogance. Like, how could she be so stupid to think that this is actually a meaningful communication? Here you have somebody who so needs a landing pad for her feelings that she’s willing to embrace it, right? And he totally misses that, he totally misses the human need and instead speaks of just evidence of this person’s stupidity rather than evidence of their humanity.
Literally, before you ever mention ELIZA again, actually try the thing. For more than 30 seconds. The illusion falls apart really, really quickly. It's not fooling anyone. What actually happened is that people tend to break into two groups. One deliberately tries to get the bot to say ridiculous things to prove what it's doing and show it off as the cheap artifice that it is. The other does just the opposite, "role-playing" and deliberately trying to avoid saying things that would cause the bot to break the roleplay, to try to get the conversation to last coherently as long as they can. Neither group is "tricked".
I'm disappointed by how little my toaster talks, and I need to remedy that situation.
If you think you can just type "Make a LLM that can run on a floppy disk", leave your session sitting there for a while with zero interaction, and come back and it's done and distributed, I have some terrible news for you...
"Tell Me You've Never Used ELIZA Without Telling Me You've Never Used ELIZA"
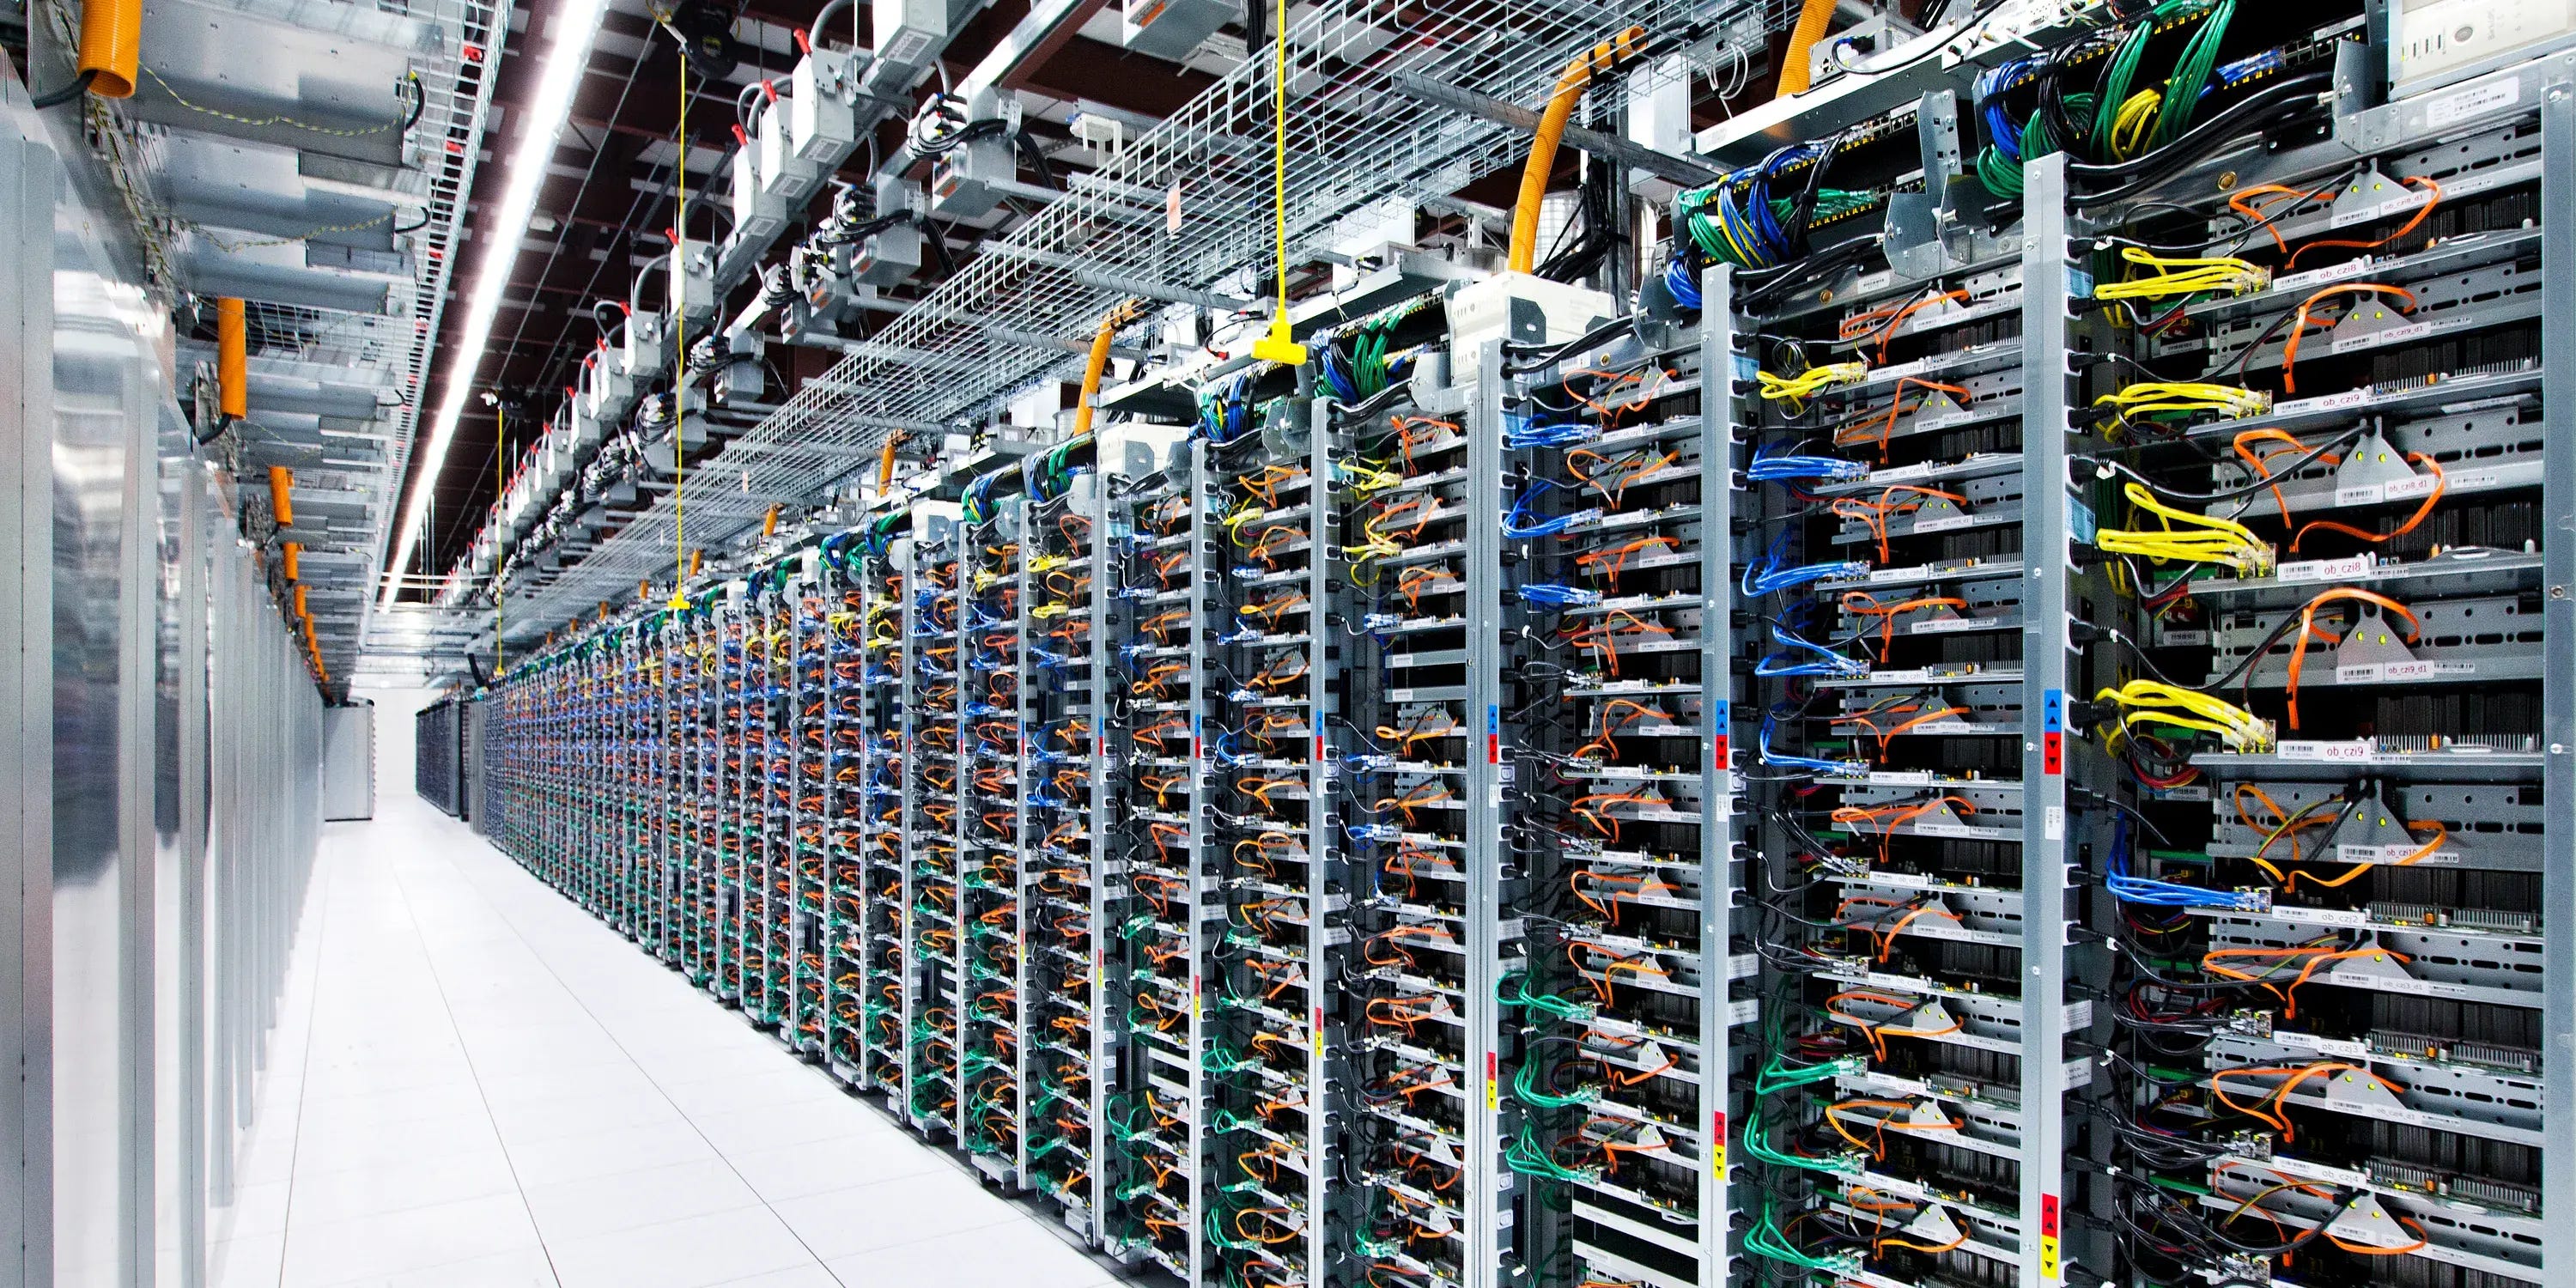
Also, can we talk for a second about how cool computers used to look?
Basically, the Cray X-MP/2 had 16-32 MB of fast RAM and a then-absurd ~5 GB/s memory bandwidth and a solid state "disk" (actually MOS RAM cache) with 256MB-1GB of storage and a 100-1000 MB/s bandwidth / sub-25-microsecond latency. The DD-39 / DD-49 disk arrays could hold 1,2GB per drive, up to 38GB, 6-10MB/s unstriped or ~50MB/s striped. Honestly, you could readily go with a far larger number of total params, so long as you kept the active params small enough to fit in RAM. An architecture like Freetoken could significantly improve performance as well. Performance would be limited by the 400 MFLOPS of compute, not the bandwidth (really, apart from the fact that all math was 64 bit float, it wasn't a bad architecture for inference!). You'd want to do token batching and maybe add a speculative decoding model to boost performance further.
Of course, you could never train a model like that on the Cray!
The funny thing is, if we could send the weights and inference back in time, a 1983 Cray X-MP/2 running a 300M–400M total / ~35M–40M active param MoE - probably similar to the reasoning capability of the computer in Wargames - could probably output 1-3 tok/s (or make an equivalent number of reasoned decisions per second with a Jev-like decision head). In Wargames, the computer seems to output at about 3 tok/s.
Who knew that that movie was technologically plausible?
"It ain't so much the things we don't know that get us in trouble. It's the things we know that ain't so." -- Artemus Ward aka Charles Farrar Brown