Average Ratings 0 Ratings
Average Ratings 0 Ratings
Similar Products
-
LM-Kit.NETLM-Kit.NET is an enterprise-grade toolkit designed for seamlessly integrating generative AI into your .NET applications, fully supporting Windows, Linux, and macOS. Empower your C# and VB.NET projects with a flexible platform that simplifies the creation and orchestration of dynamic AI agents. Leverage efficient Small Language Models for on‑device inference, reducing computational load, minimizing latency, and enhancing security by processing data locally. Experience the power of Retrieval‑Augmented Generation (RAG) to boost accuracy and relevance, while advanced AI agents simplify complex workflows and accelerate development. Native SDKs ensure smooth integration and high performance across diverse platforms. With robust support for custom AI agent development and multi‑agent orchestration, LM‑Kit.NET streamlines prototyping, deployment, and scalability—enabling you to build smarter, faster, and more secure solutions trusted by professionals worldwide.
-
kama.aikama.ai is a Responsible AI Agent platform that gives you an accurate, accountable, and safe AI for your organization. It is used for training, quick source of truth for compliance issues, internal support, customer service, and for specialized communities needs. Unlike generic GenAI tools that create answers probabilistically, kama.ai combines deterministic Knowledge Graph AI with governed Generative AI and Trusted Collections. Trusted Collections is a RAG technology that minimizes generative side hallucinations, while providing a core source for accurate, brand-safe, and a correct information source for AI answers. It lets organizations control what their AI Agents know, where answers come from, and how information is delivered to employees, customers, learners, members, or community users. kama.ai’s platform is designed for situations where answers must be accurate, traceable, brand-safe, and aligned with approved source material. Human experts and Knowledge Managers can curate content, review AI-generated drafts, manage knowledge domains, and improve responses over time. This supports a governed-in-advance approach to AI, rather than relying on after-the-fact correction. kama.ai is especially well suited for knowledge-heavy organizations, training programs, compliance environments, Indigenous and community-focused initiatives, HR support, education, research, and other use cases where trusted information matters. This platform focused on Responsible AI use and delivery, results in safer AI adoption, better knowledge access, reduced repetitive workload, and more consistent support for the people who rely on your organization’s expertise. Think kama.ai for trusted AI, governed knowledge, and answers your organization is willing to stand behind.
-
Google AI StudioGoogle AI Studio is an all-in-one environment designed for building AI-first applications with Google’s latest models. It supports Gemini, Imagen, Veo, and Gemma, allowing developers to experiment across multiple modalities in one place. The platform emphasizes vibe coding, enabling users to describe what they want and let AI handle the technical heavy lifting. Developers can generate complete, production-ready apps using natural language instructions. One-click deployment makes it easy to move from prototype to live application. Google AI Studio includes a centralized dashboard for API keys, billing, and usage tracking. Detailed logs and rate-limit insights help teams operate efficiently. SDK support for Python, Node.js, and REST APIs ensures flexibility. Quickstart guides reduce onboarding time to minutes. Overall, Google AI Studio blends experimentation, vibe coding, and scalable production into a single workflow.
-
DocmosisDocmosis is a self-hosted or SaaS template-based document generation solution. Integrate with custom-built software applications or popular third-party apps using the API. Create templates using MS Word or LibreOffice. Add plain-text placeholders to control: the insertion of text/images/tables; conditionally add/remove any content; perform calculations; loop over repeating data; format data/numbers and much more. Integrate with: Custom software built using Java, C#, Python, PHP, Ruby and more via a REST API; Low-code and no-code platforms like Appian, Bubble, Mendix, Outsystems; Third-party form builders or apps that can perform a webhook such as FormAssembly or Salesforce. Used by customers in Finance, Health, Legal, Education, Government, HR, Insurance, Logistics, and Manufacturing to generate customized letters invoices, proposals, contracts, statements, reports and more.
-
Diplomat Managed File TransferDiplomat MFT from Coviant Software is a secure and scalable managed file transfer platform that replaces manual scripts and outdated FTP with reliable, automated file delivery. It supports secure protocols like SFTP, FTPS, HTTPS, and AS2, and integrates easily with cloud services including AWS S3, Azure Blob Storage, Google Cloud, Oracle Cloud, SharePoint, Dropbox, and more. Trusted for over 20 years without a single breach, Diplomat MFT helps organizations meet compliance standards like HIPAA, HITECH, GLBA, PCI/DSS, GDPR, and DORA. Advanced security features include automated PGP encryption, MFA, IP whitelisting, and threat intelligence scanning. Still using insecure or outdated tools for critical file transfers? Diplomat MFT is the smarter alternative. Built to simplify operations, close compliance gaps, and protect your most sensitive data. Start your free trial today.
-
TinyPNGTinyPNG (by Tinify) is a free image optimization service built for developers and designers. It utilizes smart lossy compression to reduce the file sizes of JPEG, PNG, WebP, and AVIF files by up to 80% with no visible quality loss. That means faster load times, better SEO, and lower bandwidth. You can compress, convert, and resize images via a clean web interface or integrate it into your workflow with the API. The platform also provides an image CDN for fast global delivery of optimized assets. SDKs are available for Python, Node.js, PHP, Java, Ruby, and .NET. WordPress plugin included, plus plenty of community-driven integrations. No tuning, no noise, Tinify just works. Whether you're optimizing a handful of images or processing millions, it scales effortlessly. All plans include a generous free tier, and support is quick when you need it. George the panda 🐼 approves.
-
Expedience SoftwareEXPEDIENCE AUTOMATES MICROSOFT WORD PROPOSALS Use Microsoft Word to craft business proposals, RFP responses, or Statements of Work (SOWs)? Expedience delivers unmatched efficiency, flawless branding consistency, and 100% document accuracy – without ever leaving Microsoft Word! THE MICROSOFT ADVANTAGE Native to Microsoft Word, Expedience leverages the best of Microsoft 365: • Use Rich Content (tables, charts, videos, PowerPoint slides, etc) • Consistent Corporate Branding • Copilot Generative AI • Excel Data Integration • Realtime Collaboration AUTOMATED SALES PROPOSALS & SOWs Create complete Microsoft Word document proposals, sales documents, and SOWs in just a few clicks - even from Excel spreadsheets! Consistent, accurate, and perfectly formatted every time. TRUSTED CONTENT Expedience stores your curated, branded, approved content in a library for quick reuse. This means that your team will have trusted content at their fingertips directly within Microsoft Word.
-
BluehostBluehost is a popular web hosting platform that provides infrastructure and tools for building and managing websites online. The service supports multiple hosting options including shared hosting, WordPress hosting, VPS hosting, and dedicated server solutions. Bluehost offers user-friendly website creation tools such as AI-powered builders and one-click WordPress installation. Businesses and individuals can launch websites quickly with features like free SSL certificates, free domain registration for the first year, and automated updates. The platform also provides WooCommerce hosting for users who want to create and manage online stores. Built-in performance features such as CDN integration, optimized servers, and NVMe storage help ensure fast page loading speeds. Security tools including malware scanning, DDoS protection, and firewalls help keep websites protected. Bluehost also provides professional email hosting and domain management services. Users can manage their websites through an intuitive control panel with one-click plugin installations and backups. Overall, Bluehost provides a complete hosting environment for launching and scaling websites.
-
MobiPDFMobiPDF (formerly PDF Extra) is an intuitive reader and editor that allows you to read, edit, create, OCR, organize, annotate, fill and sign, convert, and share any PDF. This makes MobiPDF an excellent choice for users seeking a budget-friendly alternative to Adobe Acrobat Pro. HERE’S WHAT YOU GET WITH MOBIPDF: Multiple Page View Modes: Enjoy a distraction-free "Read Mode". Advanced Editing Tools: Experience a Word-like PDF editing environment. Two-Way Conversions: Convert PDFs to and from Word, Excel, PowerPoint, or image formats. OCR Support: Make scanned documents searchable. Markup Tools: Highlight, comment, strikethrough, stamp, and more to enhance your documents. Effortless PDF Organizer: Reorder, compress, split, and combine PDFs with ease. Sign & Secure: Add signatures, create and fill forms, and protect your PDFs with passwords, encryption, and digital certificates. Offline Mode: Work freely on your projects, even offline. Seamless translation: One-click translate any PDF into 50+ languages.
-
FlashcloudFlashcloud is a modern web hosting provider built to deliver better hosting without the usual trade-offs. Instead of cutting costs at the expense of quality, Flashcloud focuses on performance, simplicity, and real human support. Founded by a team with nearly two decades of experience, Flashcloud offers shared hosting, WordPress hosting, and VPS hosting designed for speed, reliability, and ease of use. Everything runs on a global cloud infrastructure optimized for fast load times and consistent uptime. What makes Flashcloud different is its “more included” approach. Plans come with a free starter website, free domain for life, domain privacy, daily backups, and seamless migrations — all included from day one, with no hidden extras. Switching is simple, with expert-led transfers, no downtime, and even credit for unused time with your previous provider. With transparent pricing, no surprise renewals, and support from real people whenever you need it, Flashcloud delivers a hosting experience that’s straightforward, dependable, and built around the customer. Ideal for web hosting, WordPress hosting, VPS hosting, and managed cloud hosting with everything included.
Description
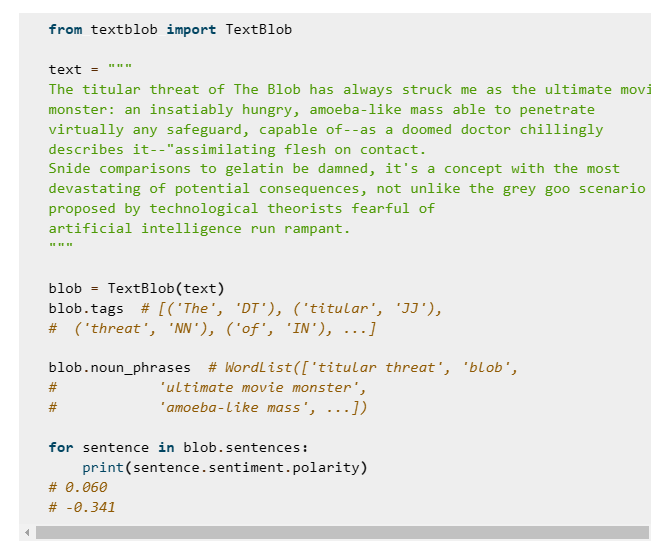
TextBlob is a Python library designed for handling textual data, providing an intuitive API to carry out various natural language processing functions such as part-of-speech tagging, sentiment analysis, noun phrase extraction, and classification tasks. Built on the foundations of NLTK and Pattern, it integrates seamlessly with both libraries. Notable features encompass tokenization (the division of text into words and sentences), frequency analysis of words and phrases, parsing capabilities, n-grams, and word inflection (both pluralization and singularization), alongside lemmatization, spelling correction, and integration with WordNet. TextBlob is compatible with Python versions 2.7 and higher, as well as 3.5 and above. The library is actively maintained on GitHub and is released under the MIT License. For users seeking guidance, thorough documentation is readily accessible, including a quick start guide and a variety of tutorials to facilitate the implementation of different NLP tasks. This rich resource equips developers with the tools necessary to enhance their text processing capabilities.
Description
pdf2docx is a Python library that leverages PyMuPDF to extract information from PDF documents, analyze their layouts based on specific rules, and create corresponding .docx files using python-docx. This library facilitates the conversion of various elements, including text, images, and tables, and is equipped with features to extract tables, manage formatting, and maintain layout integrity as much as possible. In addition, it offers a command-line interface as well as a graphical user interface to accommodate different user preferences. Its modular architecture comprises distinct packages for managing pages, layouts, tables, images, shape paths, text spans, and other components, allowing for precise control over the translation of PDF content into Word documents. Developers can take advantage of the API for batch conversion processes or seamlessly integrate it into their existing workflows. Comprehensive documentation is provided, covering installation (available from PyPI or source), usage instructions, and technical insights into layout parsing, table extraction, and the various internal modules. The project is open-source and hosted on GitHub, operating under its license and disclaiming any warranties. Overall, pdf2docx is a versatile tool that significantly streamlines the conversion process from PDF to Word format, making it an essential asset for anyone working with these file types.
API Access
Has API
Yes
API Access
Has API
Yes

Integrations
Python
Yes
GitHub
No
Microsoft Word
No
NLTK
Yes
PyMuPDF
No
PyPI
No
Integrations
Python
Yes
GitHub
Yes
Microsoft Word
Yes
NLTK
No
PyMuPDF
Yes
PyPI
Yes
Pricing Details
No price information available.
Free Trial
No
Free Version
No
Pricing Details
Free
Free Trial
No
Free Version
Yes
Deployment
Web-Based
No
On-Premises
No
iPhone App
No
iPad App
No
Android App
No
Windows
Yes
Mac
Yes
Linux
Yes
Chromebook
No
Deployment
Web-Based
Yes
On-Premises
No
iPhone App
No
iPad App
No
Android App
No
Windows
No
Mac
No
Linux
No
Chromebook
No
Customer Support
Business Hours
No
Live Rep (24/7)
No
Online Support
Yes
Customer Support
Business Hours
Yes
Live Rep (24/7)
No
Online Support
Yes
Types of Training
Training Docs
Yes
Webinars
No
Live Training (Online)
No
In Person
No
Types of Training
Training Docs
Yes
Webinars
No
Live Training (Online)
No
In Person
Yes
Vendor Details
Company Name
TextBlob
Country
United States
Website
textblob.readthedocs.io/en/dev/
Vendor Details
Company Name
Artifex
Founded
1993
Country
United States
Website
pdf2docx.readthedocs.io/en/latest/
Product Features
Natural Language Processing
Co-Reference Resolution
No
In-Database Text Analytics
No
Named Entity Recognition
No
Natural Language Generation (NLG)
No
Open Source Integrations
No
Parsing
No
Part-of-Speech Tagging
No
Sentence Segmentation
No
Stemming/Lemmatization
No
Tokenization
No
Product Features
Annotations
No
Convert to PDF
No
Digital Signature
No
Encryption
No
Merge / Append
No
PDF Reader
No
Watermarking
No
