Average Ratings 0 Ratings
Average Ratings 0 Ratings
Similar Products
-
Google Cloud PlatformGoogle Cloud is an online service that lets you create everything from simple websites to complex apps for businesses of any size. Customers who are new to the system will receive $300 in credits for testing, deploying, and running workloads. Customers can use up to 25+ products free of charge. Use Google's core data analytics and machine learning. All enterprises can use it. It is secure and fully featured. Use big data to build better products and find answers faster. You can grow from prototypes to production and even to planet-scale without worrying about reliability, capacity or performance. Virtual machines with proven performance/price advantages, to a fully-managed app development platform. High performance, scalable, resilient object storage and databases. Google's private fibre network offers the latest software-defined networking solutions. Fully managed data warehousing and data exploration, Hadoop/Spark and messaging.
-
TIMiHigh-Performance Data Engineering. Total Sovereignty. TIMi delivers the power of a complete cloud data stack—on-premises, fully sovereign, and ridiculously fast. We reject artificial vendor lock-in and hidden costs. Instead, we offer absolute peace of mind through engineering excellence, giving your team the freedom to experiment, innovate, and solve complex AI, analytics, and automation challenges in record time. Why Top Enterprises Choose TIMi? Enterprise Integration & *No-Code* ETL/Data preparation: Automate complex workflows and seamlessly link your entire stack: SAP, Salesforce, SharePoint, S3, Azure Storage, PowerBI, Tableau, etc. Unmatched Infrastructure Efficiency: Our competitors such as Databricks, Dataiku, and MS Fabric all rely on Spark—and that makes them inherently inefficient since a single €2k TIMi server outperforms a 267-node Spark cluster. TIMi process billions of rows in seconds and manage petabyte-scale data lakes at a fraction of the cost. Proven AI Leadership: Harness pioneering machine learning from the creators of the first Auto-ML engine (est. 2007). Whether deployed on-premises or via our EU-Hosted Sovereign Cloud, TIMi empowers leaders in Banking, Telecoms, Manufacturing, Retail, Defense and Government.
-
Google Cloud BigQueryBigQuery is a serverless, multicloud data warehouse that makes working with all types of data effortless, allowing you to focus on extracting valuable business insights quickly. As a central component of Google’s data cloud, it streamlines data integration, enables cost-effective and secure scaling of analytics, and offers built-in business intelligence for sharing detailed data insights. With a simple SQL interface, it also supports training and deploying machine learning models, helping to foster data-driven decision-making across your organization. Its robust performance ensures that businesses can handle increasing data volumes with minimal effort, scaling to meet the needs of growing enterprises. Gemini within BigQuery brings AI-powered tools that enhance collaboration and productivity, such as code recommendations, visual data preparation, and intelligent suggestions aimed at improving efficiency and lowering costs. The platform offers an all-in-one environment with SQL, a notebook, and a natural language-based canvas interface, catering to data professionals of all skill levels. This cohesive workspace simplifies the entire analytics journey, enabling teams to work faster and more efficiently.
-
DbVisualizerDbVisualizer is a universal database client for anyone who works with data, from indie developers and startups to professional teams managing complex database environments, including developers, DBAs, analysts, and data engineers working across relational and NoSQL databases. Key features: - SQL editor with intelligent autocomplete, visual query builders, variables, and execution tools - AI Assistant for answering questions, explaining errors, and analyzing code - Git integration for managing SQL scripts and team collaboration - Customizable layouts, key bindings, and UI themes - Favorites for frequently used scripts and database objects - Configurable security settings for organizational requirements Connects via JDBC to MySQL, PostgreSQL, SQL Server, Oracle, Snowflake, SQLite, Cassandra, BigQuery, and more. Runs on Windows, macOS, and Linux. Nearly 7 million downloads, with Pro users in 150 countries, scaling from solo projects to enterprise database management.
-
AnalyticsCreatorAnalyticsCreator is a metadata-driven design application for data warehouse automation and data product engineering across the Microsoft data stack. Its Governed Control Model connects business meaning, data structures, transformation rules, dependencies, lineage and technical implementation in one controlled project model. Data teams design the required architecture in AnalyticsCreator, then generate native Microsoft assets from that design. Generated outputs can include SQL Server objects, SSIS packages, Azure Data Factory pipelines, supported Microsoft Fabric components, deployment artefacts and Power BI semantic models. AnalyticsCreator supports dimensional, 3NF and hybrid modelling approaches together with ingestion, transformations, delta loading, historisation, Slowly Changing Dimensions, snapshots and repeatable data-processing patterns. Because generated outputs are native Microsoft technology, no AnalyticsCreator runtime is required in production. Organisations retain ownership of the resulting implementation and can integrate generated assets into Git, Azure DevOps and CI/CD workflows. Lineage, documentation and dependency information remain connected to the design, helping teams understand change impact before regenerating affected assets. Design Intelligence extends this governed project context into AI-assisted data engineering by providing authorised AI tools and agents with structured access to metadata, lineage, dependencies and design rules. Typical use cases include enterprise data warehouse development, Microsoft Fabric adoption, SQL Server and SSIS modernisation, governed Power BI delivery and repeatable data product engineering.
-
DataBuckBig Data Quality must always be verified to ensure that data is safe, accurate, and complete. Data is moved through multiple IT platforms or stored in Data Lakes. The Big Data Challenge: Data often loses its trustworthiness because of (i) Undiscovered errors in incoming data (iii). Multiple data sources that get out-of-synchrony over time (iii). Structural changes to data in downstream processes not expected downstream and (iv) multiple IT platforms (Hadoop DW, Cloud). Unexpected errors can occur when data moves between systems, such as from a Data Warehouse to a Hadoop environment, NoSQL database, or the Cloud. Data can change unexpectedly due to poor processes, ad-hoc data policies, poor data storage and control, and lack of control over certain data sources (e.g., external providers). DataBuck is an autonomous, self-learning, Big Data Quality validation tool and Data Matching tool.
-
DenodoDenodo is a logical data management platform built to help enterprises unify, govern, and deliver trusted data across complex technology environments. It connects data from cloud, on-premises, SaaS, third-party, and multi-cloud systems without copying or duplicating the information. The platform gives organizations a single trusted view of distributed data, helping analytics teams, business users, and AI agents access current information more efficiently. Denodo supports trustworthy agentic AI by combining live data access with business semantics, centralized governance, compliance controls, and lineage. Its self-service data marketplace allows users to find, prepare, and use governed data while reducing dependence on IT teams. The platform also supports natural language search, personalized data delivery, and role-specific views so users can get data with the right business meaning. Denodo helps organizations improve data lakehouse investments by giving teams optimized access to data beyond a single repository. Its real-time delivery capabilities help operations, analytics, and AI systems make decisions based on current information instead of stale copies. By reducing integration time and improving time-to-insight, Denodo gives enterprises a trusted data foundation for AI, analytics, and digital transformation.
-
SCIKIQSCIKIQ is one of the most innovative AI-native Data & Intelligence platforms for enterprises, built to make enterprise data AI-ready in weeks, not years. Recognized by Forrester among leading AI-augmented data platforms, NASSCOM League of 10, YourStory Tech30, Inc42 and DataIQ, SCIKIQ is trusted by leading global enterprises across the USA, India, and UAE. SCIKIQ brings Data Integration, Data Quality, Data Governance, Metadata Management, Data Lineage, Semantic Intelligence, Knowledge Graphs, Conversational Analytics, Generative AI, Data Products and AI Agents together in one unified platform. Unlike traditional data platforms that require enterprises to move or rebuild their technology stack, SCIKIQ works with what you already have. Connect SAP, Salesforce, Oracle, Snowflake, Databricks, AWS, Azure, GCP, data lakes, warehouses and enterprise applications through 200+ pre-built connectors, with no rip-and-replace. What makes SCIKIQ different is Contextual Intelligence. SCIKIQ doesn't just connect data; it helps AI understand its business meaning. Its semantic layer combines business terms, KPI definitions, metadata, lineage, ownership, rules, ontologies and relationships to create a trusted foundation for enterprise AI. Business users can talk to their data in natural language, investigate KPIs, discover root causes and generate insights without SQL. Data teams gain enterprise-grade governance, quality, lineage and control. AI teams get trusted, contextual data for building GenAI applications and intelligent AI agents. Why enterprises choose SCIKIQ AI-ready in 3–6 weeks | 167+ connectors | 99.9% availability | Multi-cloud | No-code | No vendor lock-in | No replatforming Proven production deployments across Manufacturing retail, airlines, logistics, BFSI
-
RaimaDBRaimaDB, an embedded time series database that can be used for Edge and IoT devices, can run in-memory. It is a lightweight, secure, and extremely powerful RDBMS. It has been field tested by more than 20 000 developers around the world and has been deployed in excess of 25 000 000 times. RaimaDB is a high-performance, cross-platform embedded database optimized for mission-critical applications in industries such as IoT and edge computing. Its lightweight design makes it ideal for resource-constrained environments, supporting both in-memory and persistent storage options. RaimaDB offers flexible data modeling, including traditional relational models and direct relationships through network model sets. With ACID-compliant transactions and advanced indexing methods like B+Tree, Hash Table, R-Tree, and AVL-Tree, it ensures data reliability and efficiency. Built for real-time processing, it incorporates multi-version concurrency control (MVCC) and snapshot isolation, making it a robust solution for applications demanding speed and reliability.
-
Servers.com by NexcessServers.com by Nexcess delivers hybrid bare metal cloud hosting solutions that give businesses greater control over their infrastructure while maintaining the flexibility needed to grow. Its portfolio includes Scalable Bare Metal for on-demand capacity, Enterprise Bare Metal for customized deployments, AI Compute for GPU-powered workloads, and Managed Kubernetes for containerized applications. The platform is built to accommodate organizations that require reliable performance, security, and predictable infrastructure management. Through a network of data centers across multiple continents, customers can deploy services closer to their users and minimize latency. Businesses in industries such as gaming, financial services, advertising technology, streaming, SaaS, and Web3 rely on the platform to support high-demand operations. The infrastructure is designed to handle traffic spikes, intensive computing requirements, and geographically distributed workloads. Advanced networking capabilities and direct connectivity options help optimize application responsiveness and uptime. Organizations can combine different infrastructure offerings to create environments that align with their operational and budget requirements. By providing scalable and customizable bare metal solutions, Servers.com helps businesses maintain performance while adapting to changing market demands.
Description
Apache Spark™ serves as a comprehensive analytics platform designed for large-scale data processing. It delivers exceptional performance for both batch and streaming data by employing an advanced Directed Acyclic Graph (DAG) scheduler, a sophisticated query optimizer, and a robust execution engine. With over 80 high-level operators available, Spark simplifies the development of parallel applications. Additionally, it supports interactive use through various shells including Scala, Python, R, and SQL. Spark supports a rich ecosystem of libraries such as SQL and DataFrames, MLlib for machine learning, GraphX, and Spark Streaming, allowing for seamless integration within a single application. It is compatible with various environments, including Hadoop, Apache Mesos, Kubernetes, and standalone setups, as well as cloud deployments. Furthermore, Spark can connect to a multitude of data sources, enabling access to data stored in systems like HDFS, Alluxio, Apache Cassandra, Apache HBase, and Apache Hive, among many others. This versatility makes Spark an invaluable tool for organizations looking to harness the power of large-scale data analytics.
Description
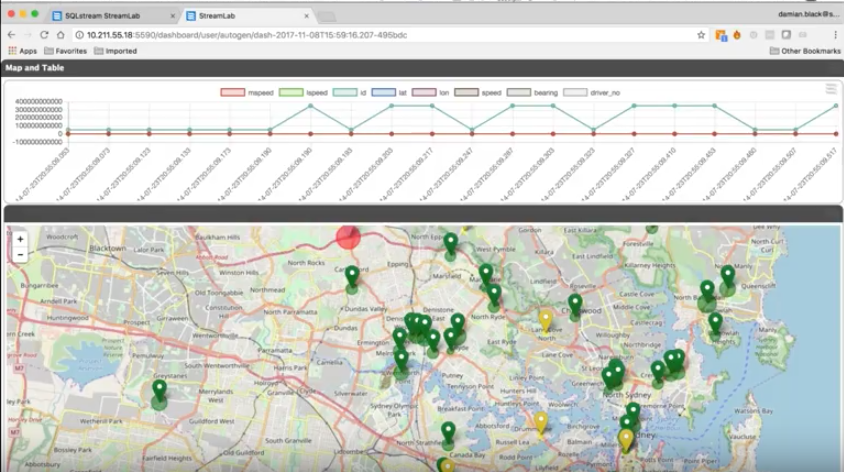
In the field of IoT stream processing and analytics, SQLstream ranks #1 according to ABI Research. Used by Verizon, Walmart, Cisco, and Amazon, our technology powers applications on premises, in the cloud, and at the edge.
SQLstream enables time-critical alerts, live dashboards, and real-time action with sub-millisecond latency. Smart cities can reroute ambulances and fire trucks or optimize traffic light timing based on real-time conditions. Security systems can detect hackers and fraudsters, shutting them down right away. AI / ML models, trained with streaming sensor data, can predict equipment failures.
Thanks to SQLstream's lightning performance -- up to 13 million rows / second / CPU core -- companies have drastically reduced their footprint and cost. Our efficient, in-memory processing allows operations at the edge that would otherwise be impossible.
Acquire, prepare, analyze, and act on data in any format from any source. Create pipelines in minutes not months with StreamLab, our interactive, low-code, GUI dev environment. Edit scripts instantly and view instantaneous results without compiling. Deploy with native Kubernetes support.
Easy installation includes Docker, AWS, Azure, Linux, VMWare, and more
API Access
Has API
No
API Access
Has API
Yes




Integrations
Amazon EC2
Yes
Apache Hive
Yes
Apache Mahout
Yes
Apache Zeppelin
Yes
Azure Data Science Virtual Machines
Yes
DataNimbus
Yes
Kedro
Yes
Kylo
Yes
Lyftrondata
Yes
MLlib
Yes
Integrations
Amazon EC2
No
Apache Hive
No
Apache Mahout
No
Apache Zeppelin
No
Azure Data Science Virtual Machines
No
DataNimbus
No
Kedro
No
Kylo
No
Lyftrondata
No
MLlib
No
Pricing Details
No price information available.
Free Trial
No
Free Version
Yes
Pricing Details
No price information available.
Free Trial
Yes
Free Version
Yes
Deployment
Web-Based
Yes
On-Premises
No
iPhone App
No
iPad App
No
Android App
No
Windows
No
Mac
No
Linux
No
Chromebook
No
Deployment
Web-Based
Yes
On-Premises
No
iPhone App
No
iPad App
No
Android App
No
Windows
Yes
Mac
No
Linux
Yes
Chromebook
No
Customer Support
Business Hours
No
Live Rep (24/7)
No
Online Support
No
Customer Support
Business Hours
Yes
Live Rep (24/7)
Yes
Online Support
Yes
Types of Training
Training Docs
Yes
Webinars
No
Live Training (Online)
No
In Person
No
Types of Training
Training Docs
Yes
Webinars
Yes
Live Training (Online)
Yes
In Person
Yes
Vendor Details
Company Name
Apache Software Foundation
Founded
1999
Country
United States
Website
spark.apache.org
Vendor Details
Company Name
Guavus, a Thales company
Founded
2006
Country
United States
Website
sqlstream.com
Product Features
Big Data
Collaboration
No
Data Blends
No
Data Cleansing
No
Data Mining
No
Data Visualization
No
Data Warehousing
No
High Volume Processing
No
No-Code Sandbox
No
Predictive Analytics
No
Templates
No
Data Analysis
Data Discovery
No
Data Visualization
No
High Volume Processing
No
Predictive Analytics
No
Regression Analysis
No
Sentiment Analysis
No
Statistical Modeling
No
Text Analytics
No
Streaming Analytics
Data Enrichment
Yes
Data Wrangling / Data Prep
Yes
Multiple Data Source Support
Yes
Process Automation
Yes
Real-time Analysis / Reporting
No
Visualization Dashboards
No
Product Features
Streaming Analytics
Data Enrichment
Yes
Data Wrangling / Data Prep
Yes
Multiple Data Source Support
Yes
Process Automation
Yes
Real-time Analysis / Reporting
Yes
Visualization Dashboards
Yes
